EN ES FR ID
3.2.1 Simple blocking for caches, part 1 3:22
📺 LAFF-On Programming for High Performance • 👁️ 781 views
3.2.4 Blocking for the L1 and L2 caches 8:13
📺 LAFF-On Programming for High Performance • 👁️ 770 views

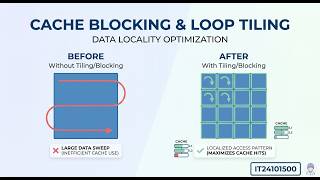
It24101500 Cache Blocking Loop Tiling Parallel Computing Information Guide

  1. Introduction on It24101500 Cache Blocking Loop Tiling Parallel Computing
  2. Key Details
  3. Recent Updates
  4. Expert Insights
  5. Conclusion

Introduction on It24101500 Cache Blocking Loop Tiling Parallel Computing

Details It24101500 | Cache Blocking | Loop Tiling | Parallel Computing News
Looking for the latest information on It24101500 Cache Blocking Loop Tiling Parallel Computing? We've gathered comprehensive data, records, and insights about It24101500 Cache Blocking Loop Tiling Parallel Computing.

Key Details

Details Performance x64: Cache Blocking (Matrix Blocking) Update
Explore the main sources for It24101500 Cache Blocking Loop Tiling Parallel Computing.

Recent Updates

Information Defensive Loop Tiling for Shared Cache News
Stay updated on It24101500 Cache Blocking Loop Tiling Parallel Computing's latest milestones.

Loop Optimizations: Vectorization, Register Blocking, Roofline Model and Loop Tiling
Cache Blocking using Tiling in a Molecular Dynamics Application Benny Mathew and Manoj Nambiar
3.2.4 Blocking for the L1 and L2 caches
Episode 5.13 - Example of Loop Tiling
Same Loop, 10× Slower CPU Caches Explained: Cache Lines, Locality & Loop Order | HPC Lecture 10
3.2.5 Blocking for the L1, L2, and L3 caches
Tiling - Intro to Parallel Programming
Must Know Technique in GPU Computing | Episode 4: Tiled Matrix Multiplication in CUDA C
Compiler Design Module 165 : Blocking for Fully Permutable Loops
CPU Caches and Locality, Explained: Why Loop Order Makes Code 30x Slower

Expert Insights

Data is compiled from public records and verified media reports.

Last Updated: November 12, 2026

Conclusion

Full 3.2.1 Simple blocking for caches, part 1 Guide
For 2026, It24101500 Cache Blocking Loop Tiling Parallel Computing remains one of the most searched-for information profiles. Check back for the newest reports.

Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
🔥 Trending Topics

Louise Carmen Heritage Journal Akron Beacon Journal Account Akron Beacon Journal Alterra Akron Beacon Journal App Akron Beacon Journal Archives Free Akron Beacon Journal Archives Obituaries Akron Beacon Journal Articles Akron Beacon Journal Athlete Of The Week Akron Beacon Journal Athlete Of The Year Akron Beacon Journal Bath Shooting Akron Beacon Journal Best Of The Best Akron Beacon Journal Bigfoot Akron Beacon Journal Billing Akron Beacon Journal Breaking News Akron Beacon Journal Browns Akron Beacon Journal Building Akron Beacon Journal Burger Bracket Akron Beacon Journal Circulation Manager Akron Beacon Journal Circulation Phone Number Akron Beacon Journal Classifieds
Advertisement